
Node Autoscaler preparation checklist
The recommended way to prepare a newly-connected cluster for Node Autoscaling is to run castctl cluster import-config. It discovers your existing node group configuration from your cloud provider and creates matching node configurations and node templates automatically, so Cast AI provisions nodes that match what you already run. This is the fastest, least error-prone way to get a working setup. See Import and apply cluster configuration with castctl for the full guide.
castctl cluster import-configAutomated import handles node-level configuration. It doesn't, and can't, change how your workloads are deployed, so review the requirements below regardless of which path you take.
Before enabling Node Autoscaling in production
Cast AI's Node Autoscaler and Evictor work by provisioning and removing nodes, and by evicting and rescheduling pods. Workloads that don't follow Kubernetes best practices can experience unexpected downtime when automation is active.
Before enabling Node Autoscaling on a production cluster, verify that your workloads meet the following requirements:
| Requirement | Why it matters |
|---|---|
| PodDisruptionBudgets (PDBs) configured for all critical workloads | Without a PDB, Evictor may evict all pods of a deployment simultaneously. A PDB with minAvailable: 1 is the minimum recommended setting. See PodDisruptionBudgets. |
imagePullPolicy is not Always unless required | Always introduces delays when pods are rescheduled to new nodes, and will fail entirely if the registry is temporarily unreachable. |
| Startup probes configured for services with slow initialization | JVM-based services and other slow-starting workloads should have startup probes to prevent traffic routing before the app is ready. This is a best practice rather than a hard requirement. |
| Stateful workloads reviewed individually | Databases, caches, and message queues must have data replication in place and be able to tolerate pod restarts. |
Pod startup times are compatible with nodeGracePeriodMinutes | The default grace period before Evictor targets a new node is 5 minutes. Workloads with slow startup times may need this value increased. |
TipEnable and validate Node Autoscaling in a staging or development environment with representative workloads before rolling it out to production. See the Evictor documentation for more details on production readiness.
Goals
- Upscale the cluster during peak hours.
- Binpack or downscale the cluster when excess capacity is no longer required.
- Use Spot Instances to reduce your infrastructure costs, but have the safety of on-demand instances when needed.
General guidelines: manual node configuration
castctl cluster import-config sets up the policies below for you automatically, based on your cluster's existing configuration. The rest of this section explains what it configures and why, for reference. Use it if you're configuring node templates manually, or if you want to understand what automated import sets up on your behalf.
Unscheduled pods policy
To upscale a cluster, Cast AI needs to react to unschedulable pods. You can achieve this by turning on the Unscheduled Pods policy and configuring the Default Node template.
What is an unschedulable pod?This term refers to a pod stuck in a pending state, meaning that it cannot be scheduled onto a node. Generally, this is because insufficient resources of one type or another prevent scheduling.
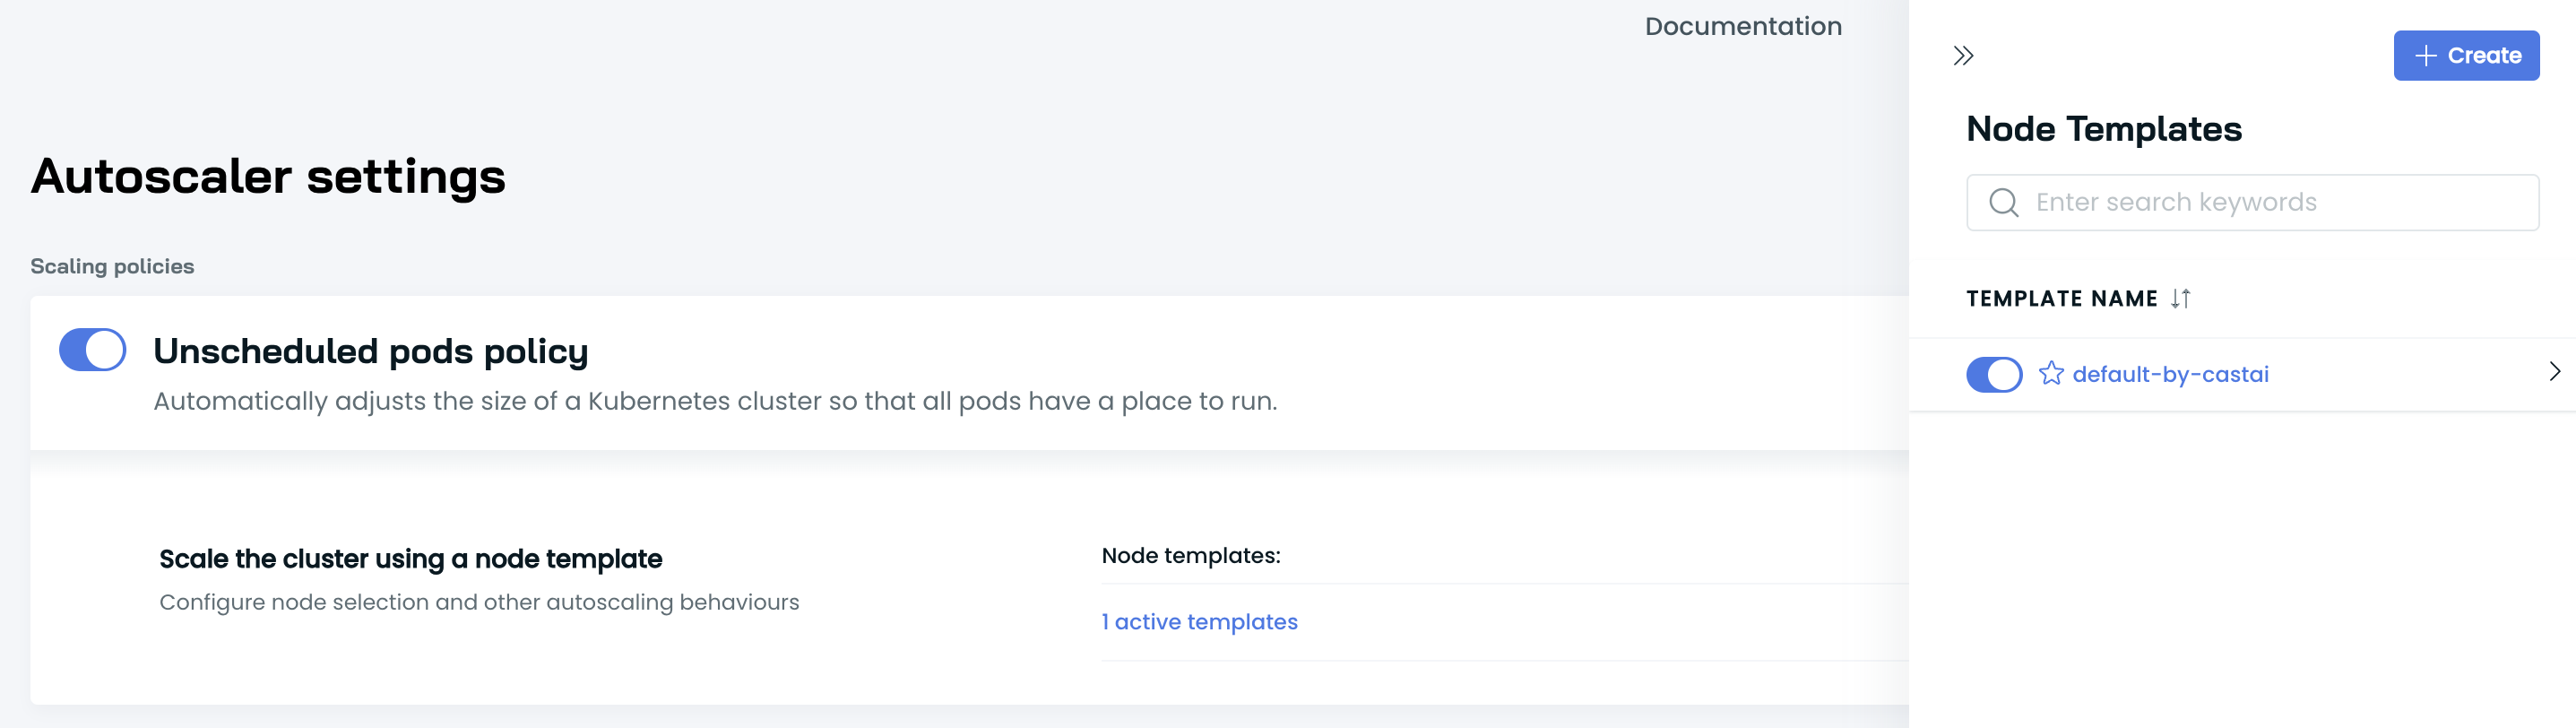
Unscheduled pods policy with Default Node template
Why?
- Automatically adds the required capacity to the cluster.
- Enables Spot instances, so Cast AI can handle spot instances and their interruptions for you.
- Enables Spot Fallbacks to automatically switch back and forth to on-demand capacity when spot isn't available in your cloud environment.
Node deletion policy / Evictor
Cast AI can constantly binpack the cluster and remove any excess capacity. To achieve this, we recommend the following initial setup:
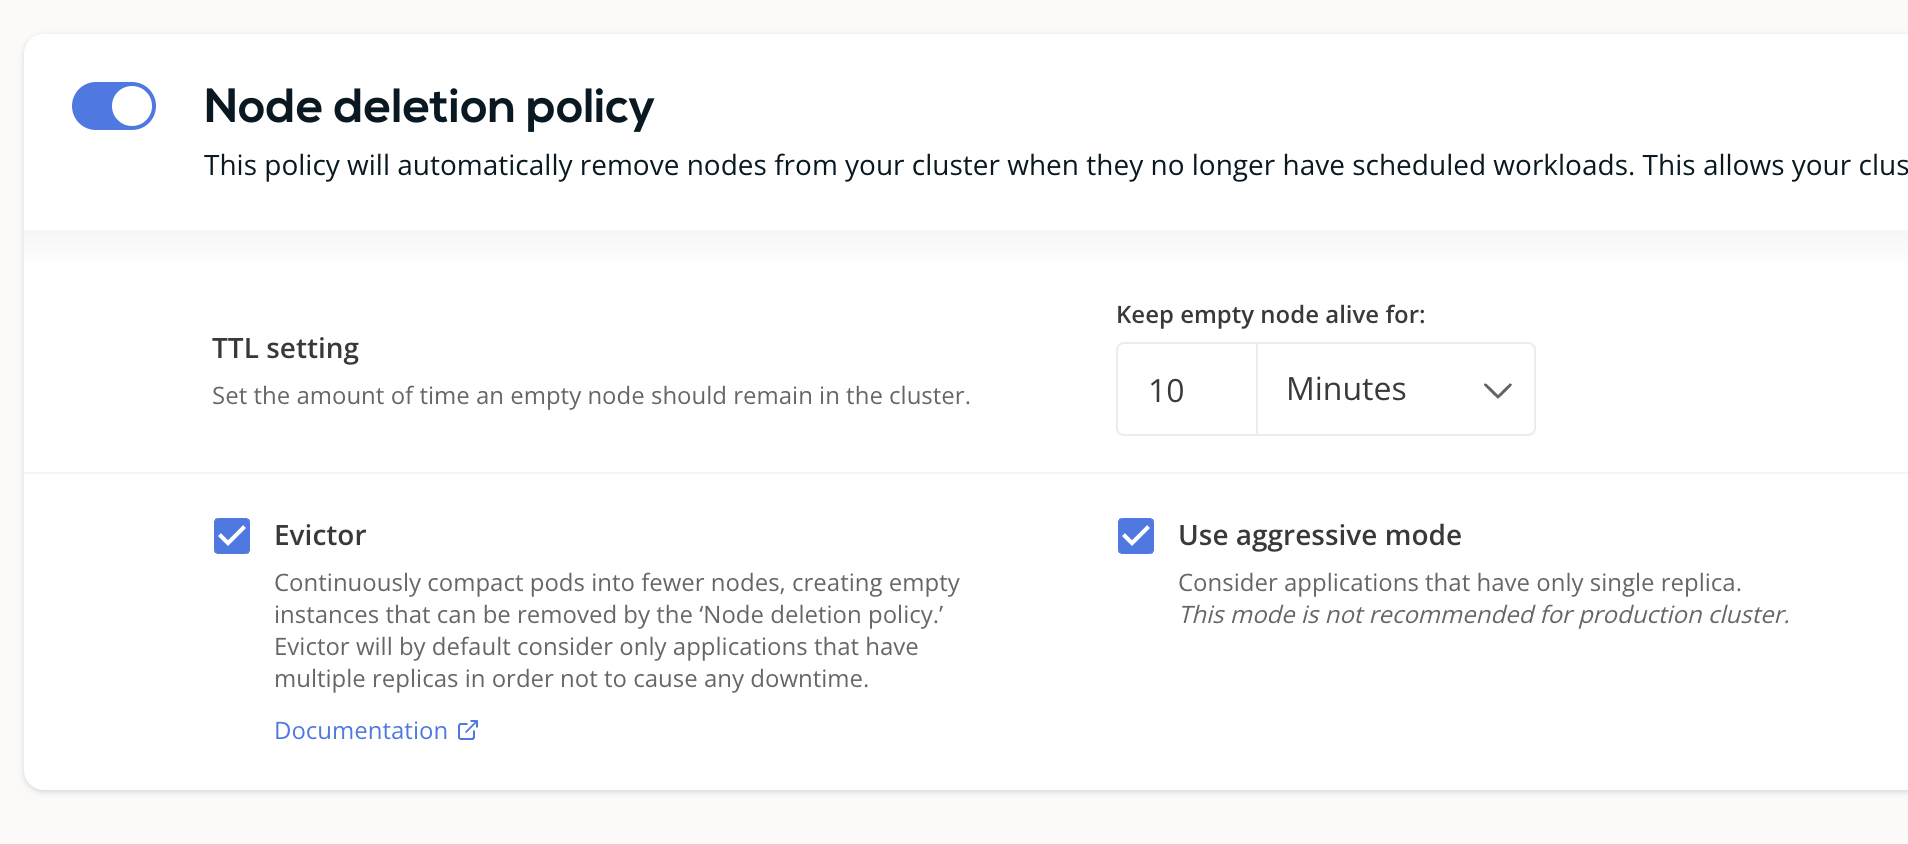
Node deletion policy recommended settings
Why?
- Ensures that empty nodes don't keep running in the cluster longer than the configured duration.
- Enables Evictor for higher node resource utilization and less waste. Evictor continuously simulates scenarios where it tries to eliminate underutilized nodes by checking whether the pods could be scheduled in the remaining capacity. Simulation respects PDBs and all other Kubernetes restrictions. Configure PDBs for all critical workloads before enabling Evictor. Without a PDB, there's no guarantee that at least one replica remains available during bin-packing.
What is Evictor's aggressive mode?When Evictor runs in aggressive mode, it considers workloads with a single replica as potential targets for binpacking. This might cause some disruption in single-replica workloads.
Validate the setup
After enabling Node Autoscaling, whether through automated import or manual configuration, run a simple upscale/downscale test to confirm the Node Autoscaler reacts as expected:
-
Deploy a test workload that requires Spot capacity:
kubectl apply -f https://raw.githubusercontent.com/castai/examples/main/evictor-demo-pods/test_pod_spot.yaml# https://github.com/castai/examples/blob/main/evictor-demo-pods/test_pod_spot.yaml apiVersion: apps/v1 kind: Deployment metadata: name: castai-test-spot namespace: castai-agent labels: app: castai-test-spot spec: replicas: 10 selector: matchLabels: app: castai-test-spot template: metadata: labels: app: castai-test-spot spec: tolerations: - key: scheduling.cast.ai/spot operator: Exists nodeSelector: scheduling.cast.ai/spot: "true" containers: - name: nginx image: nginx:latest ports: - containerPort: 80 resources: requests: cpu: 4This confirms Cast AI has what it needs to upscale the cluster automatically.
-
Once capacity is added, check that your DaemonSet pod count matches the node count:
# Get DaemonSets in all namespaces kubectl get ds -A # Get node count kubectl get nodes | grep -v NAME | wc -l -
Confirm the deployed pod is
Running, then scale it back down:kubectl scale deployment/castai-test-spot --replicas=0Verify that Cast AI removes the now-empty nodes within the configured time interval.
Troubleshooting
Partially managed by Cast AI
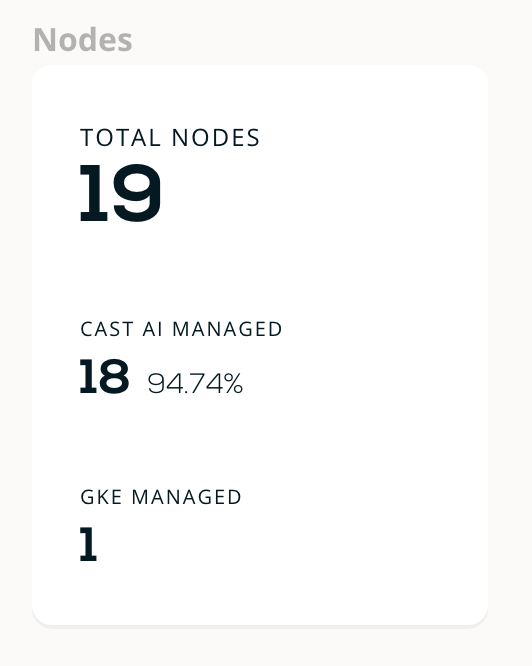
One node not managed by Cast AI
When you connect a cluster, it may not be immediately fully managed by Cast AI: some workloads can still run on existing legacy node pools or Autoscaling groups outside Cast AI's control.
- Recommended: run
castctl cluster import-configto translate those legacy node pools into matching Cast AI node configurations and node templates, bringing them under management instead of excluding them. See Import and apply cluster configuration with castctl. - Alternative: add
autoscaling.cast.ai/removal-disabled="true"on such node pools/Autoscaling groups so Cast AI excludes those nodes from Evictor and Rebalancer instead of managing them.
See also
Updated 10 days ago