
Scheduled rebalancing
How it works
Scheduled rebalancing enables full or partial rebalancing process on a user-defined schedule, scope, and trigger to automate various use cases. Most commonly scheduled rebalancing is used in the following scenarios:
- Identify the most expensive Spot Instances and replace them with cheaper alternatives
- Perform full rebalancing of clusters on weekends
- Roll old nodes
- Periodically target and replace nodes with specific labels
A rebalancing schedule is an organization-wide object that can be assigned to one or multiple clusters. Once triggered, it creates a rebalancing plan scoped by parameters provided in the node selection preferences, while the problematic workloads are excluded automatically.
To set up scheduled rebalancing, navigate to the organizational-level Optimization menu or access the Rebalancer view within the cluster.
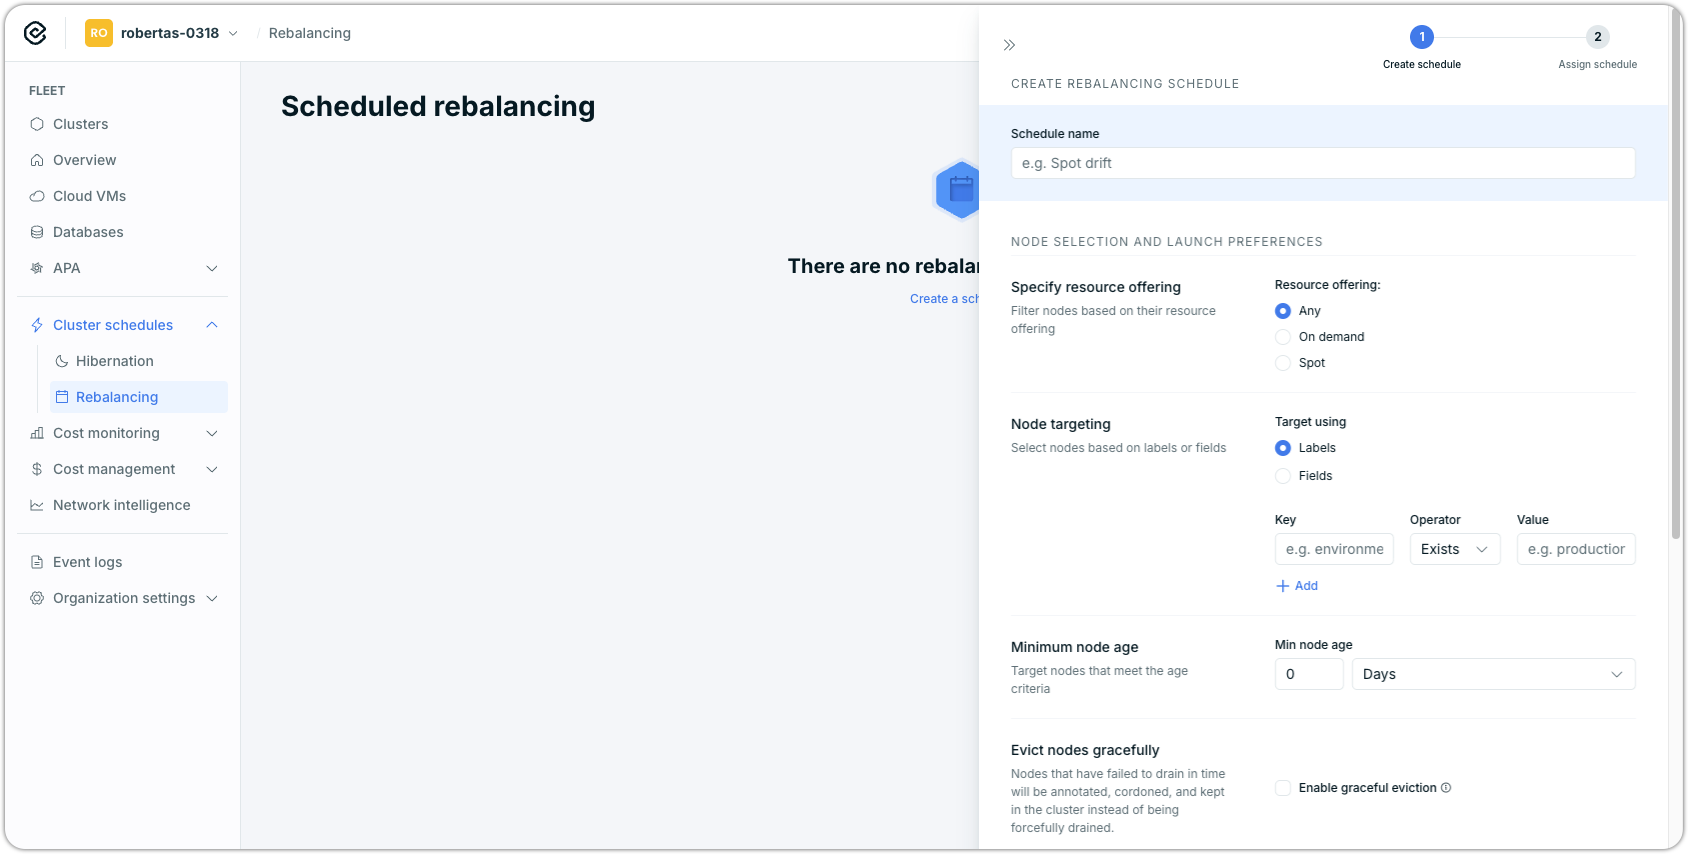
Rebalancing schedules view with the schedule creation drawer open
Setup
There are two main components in the scheduled rebalancing functionality
- A rebalancing job is a job that triggers a rebalancing schedule on an associated cluster.
- Rebalancing schedule - an organization-wide rebalancing schedule that can be used on multiple rebalancing jobs.
The Rebalancing schedule consists of four parts:
- The schedule describes when to run the scheduling (periodically, within the maintenance window, etc.)
- Node selection preferences contain rules for picking specific nodes, how many to target, and similar rules that mimic decision-making when manually rebalancing a cluster.
- Trigger requirements are decision rules for executing the rebalancing plan. They include rules like the “Savings threshold,” determining whether the generated plan should be executed.
- Execution safeguard: Cast AI stops rebalancing before draining the original nodes if it finds that the user-specified minimum level of savings can't be achieved. This additional protection layer is required as planned nodes might temporarily be unavailable in the cloud provider's inventory during the rebalancing.
Settings
The following settings can be adjusted when setting up the scheduled rebalancing:
| Setting | Description |
|---|---|
| Specify resource offering | Spot, On-Demand, or Any |
| Target using labels | Key-value pairs are provided as For |
| Minimum node age | Amount of time since the node creation before the node can be considered for rebalancing. 0 - means a node of any age can be considered. |
| Evict nodes gracefully | Defines whether nodes that fail to drain within a configurable timeout (default: 20 minutes, maximum: 180 minutes) will be kept with a When disabled (default): Nodes are forcefully drained after the timeout, which may override Pod Disruption Budgets (PDBs) to complete the rebalancing operation. When enabled: Nodes are annotated, cordoned, and kept in the cluster. PDBs are strictly respected. Cast AI automatically uncordons drain-failed Nodes after 30 minutes by default; the delay is configurable via Enable via the API by setting |
| Drain timeout | Maximum time to wait for each node to drain during rebalancing. Default: 20 minutes. Maximum: 180 minutes (10800 seconds). Default: 20 minutes. Configure this in Advanced settings when setting up a rebalancing schedule. After this timeout expires, the node is either forcefully drained (default) or annotated and kept in the cluster (when Evict nodes gracefully is enabled). |
| Maximum simultaneous drains | Maximum number of nodes to drain at the same time (API: maxSimultaneousDrains, Terraform: max_simultaneous_drains). Default: unlimited. |
| Batch execution | The value paces execution into batches so that at most this many extra nodes (created minus drained) are alive at any moment (API: splitNodesInBatchesOf, Terraform: split_nodes_in_batches_of). The plan drains a node only after its replacement node exists. When unset, zero, or negative, the plan executes in a single batch. Unlike Maximum batch size, which caps how many nodes the rebalancing plan may target, batching does not change node selection; it only paces execution. |
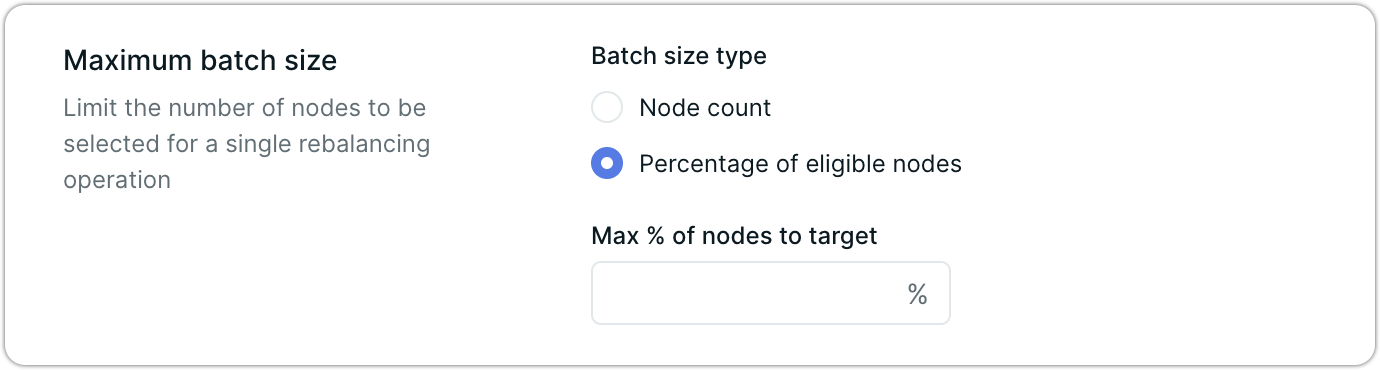
| Maximum batch size | Maximum number of nodes that can be selected for a single rebalancing operation. Use the Batch size type selector in the schedule form to set the limit in one of two ways:
|
| Sort selected nodes | The algorithm used to sort selected nodes:
|
| Aggressive mode | Defines whether rebalancing may also target nodes running problematic workloads. In the console, Enable Aggressive mode reveals the per-category options listed in Aggressive mode configuration. The deprecated aggressiveMode boolean is not offered in the console; it remains available via the API (Terraform: aggressive_mode) only. |
| Savings threshold |
|
| Execution times | Execution time can be adjusted by providing a timezone and a crontab expression |
Node targeting
When configuring node targeting for scheduled rebalancing, you can choose between two methods: Labels or Fields. This selection determines how you'll identify nodes for the rebalancing operation.
Using labels
To configure label-based targeting:
- Select "Labels" under "Target using"
- Configure your label-matching rules:
- Key: Enter the Kubernetes label key (e.g.,
scheduling.cast.ai) - Operator: Choose from:
Exists: Match nodes where the label existsDoesNotExist: Match nodes where the label is absentIn: Match nodes where the label value matches one in a listNotIn: Match nodes where the label value doesn't match any in a list
- Value: Enter the label value to match (required for
InandNotInoperators)
- Key: Enter the Kubernetes label key (e.g.,
- Add additional label-matching expressions using the "+ Add" button if needed
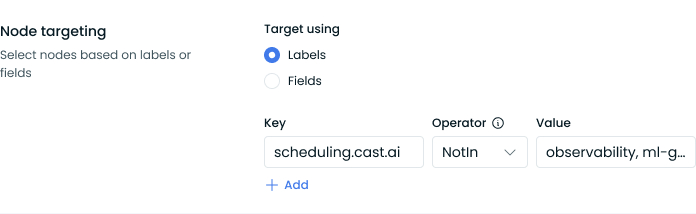
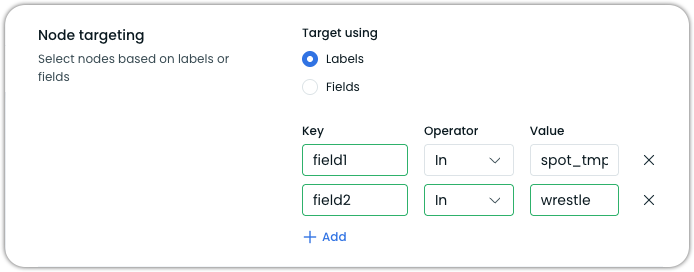
Multiple node label matching expressions are combined using the AND logic – nodes must match all specified conditions to be selected for rebalancing.
For example, if you configure:
field1Inspot_tmpfield2Inwrestle
Only nodes with both field1=spot_tmp AND field2=wrestle will be selected.
Technical details
Under the hood, the Console UI creates a single nodeSelectorTerm with multiple matchExpressions. According to Kubernetes selector logic:
- All expressions within a
nodeSelectorTermare ANDed together - Multiple
nodeSelectorTermsare ORed together (API-only, see below)
Using fields
Field-based targeting provides an alternative method when label-based selection isn't sufficient. When selecting Fields, you can target nodes based on their Kubernetes field values rather than labels.
Example
An example use case for field targeting is rebalancing a specific node by name. This is useful when you've identified a particular node that needs replacement. For example, a node running an outdated configuration or one flagged for maintenance.
- Select Fields under Target using
- Configure the field selector:
- Key:
metadata.name - Operator:
= - Value: the name of the node to target (e.g.,
ip-10-0-1-42.ec2.internal)
- Key:
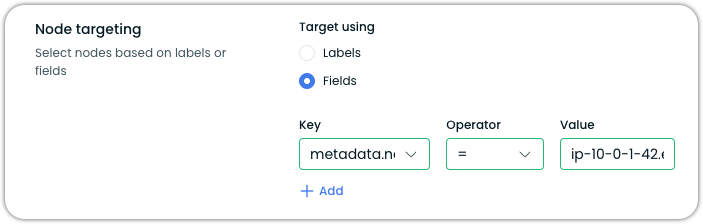
This configuration targets a single node by its Kubernetes node name, allowing you to schedule its replacement without affecting other nodes in the cluster.
For more information on using field selectors, refer to Kubernetes documentation.
Known limitation: cordoned-node targeting may cause schedules to be skippedTargeting cordoned Nodes with
spec.unschedulable=truecan cause the scheduled rebalancing operation to be skipped entirely rather than rebalancing the targeted Nodes. Cast AI automatically uncordons drain-failed Nodes after 30 minutes by default (configurable viadrainFailureConfig), but scheduled rebalancing still skips them while cordoned.For recovery options, see Handling failed Node drains.
Using OR conditions for node labels in scheduled rebalancing
OR conditions for node labels in scheduled rebalancingThe console UI supports AND logic only. To use OR conditions between node label values, use the Cast AI API:
- Use the Cast AI API endpoint for creating rebalancing schedules:
POST /v1/rebalancing-schedules - Specify multiple
nodeSelectorTermsin your request to createORlogic between terms - Within each term, use
matchExpressionswith theInoperator to target multiple values for the same label key
Example: OR logic for multiple values of the same label
"nodeSelectorTerms": [
  {
    "matchExpressions": [
      {
        "key": "nodetemplate",
        "operator": "In",
        "values": ["customerA", "customerB", "customerC"]
      }
    ]
  }
]
This configuration targets nodes with the nodetemplate label matching any of the specified values (customerA OR customerB OR customerC).
Example: OR logic between different label conditions
To create OR logic between multiple distinct label conditions, add multiple objects to the nodeSelectorTerms array:
"nodeSelectorTerms": [
  {
    "matchExpressions": [
      {
        "key": "nodetemplate1",
        "operator": "In",
        "values": ["customerA"]
      }
    ]
  },
  {
    "matchExpressions": [
      {
        "key": "nodetemplate2",
        "operator": "In",
        "values": ["customberB"]
      }
    ]
  }
]
This selects nodes with either nodetemplate=customerA OR nodetemplate2=customerB.
WarningWhen using multiple
nodeSelectorTermsvia the API, the UI may not display all values correctly. The UI is limited to displaying a single term with AND logic only.
For complete details, refer to the Cast AI API reference documentation for creating rebalancing schedules.
Maximum batch size
The Maximum batch size setting limits how many nodes a single rebalancing operation can select. In the schedule form, use the Batch size type selector to set the limit in one of two ways:
- Node count — the maximum number of nodes to target in a single operation.
0means all matching nodes in the cluster can be selected. - Percentage of eligible nodes — caps each rebalancing operation at a percentage of the eligible nodes, regardless of cluster size. This allows reusing one schedule across clusters that change in size. The percentage is rounded up to a whole number of nodes, with at least one node selected. When set, it takes precedence over the node count.
Sort selected nodes
When configuring scheduled rebalancing, the Sort selected nodes setting determines how nodes are prioritized for rebalancing. Each algorithm serves different optimization goals.
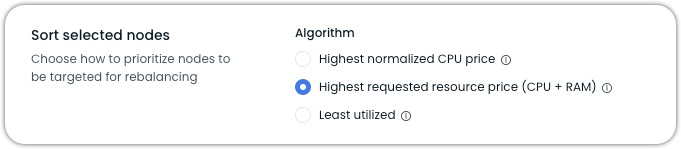
Highest normalized CPU price
- Sorts nodes by dividing the node's total cost by its CPU count, which prioritizes removing expensive nodes based on their provisioned (total available) CPUs.
- Best for: Spot Instance clusters when you want to remove the most expensive instances or a partial rebalancing where you just want to remove the most expensive nodes
NoteIt doesn't consider actual resource utilization, only the raw cost per CPU.
Highest requested resource price (CPU + RAM)
- Sorts nodes by calculating the cost of actually requested (used) resources, considering both CPU and memory in a 1:7 ratio. For example, a $5/hour node using 1 CPU and 7GB RAM has a resource price of $2.50/unit, while the same node using 4 CPU and 28GB RAM has a resource price of $0.63/unit.
- Best for: Most scenarios, especially mixed workloads with varying memory and CPU needs, as it provides the best overall cost optimization by targeting nodes with the highest wasted resource cost.
Least utilized
- Sorts nodes purely based on CPU utilization percentage, regardless of node size or cost. For example, a 2-core node with 1 core used (50% utilized) would be prioritized over a 64-core node with 20 cores used (31% utilized), even though the larger node has more wasted resources
- Best for: Specific use cases where you want to consolidate many small, underutilized nodes, regardless of cost impact
NoteIt may miss opportunities to remove larger, more expensive nodes that have higher percentage utilization but more wasted resources as a sum.
For most cost optimization scenarios, the Highest requested resource price (CPU + RAM) sorting algorithm provides the best balance for removing expensive and underutilized nodes.
Aggressive mode configuration
By default, the Rebalancer treats nodes running problematic workloads as not ready for rebalancing. Aggressive mode lifts these protections. Rebalancing can then also target nodes running pods without a controller, job pods, pods with the removal-disabled annotation, and pods annotated with rebalancing.cast.ai/prevented-drain=true.
In the console, the rebalancing schedule form groups these options under Aggressive mode.
The standalone aggressiveMode boolean is deprecated. Use aggressiveModeConfig instead: it enables aggressive rebalancing on its own and lets you choose exactly which problematic workload categories rebalancing may evict:
aggressiveModeConfig field | Workloads rebalancing may then evict |
|---|---|
ignoreProblemPodsWithoutController | Pods without a controller (bare pods); no controller exists to restart them after eviction. |
ignoreProblemJobPods | Pods that belong to Jobs or CronJobs; eviction loses their progress. |
ignoreProblemRemovalDisabledPods | Pods marked with the removal-disabled annotation. |
ignoreProblemPreventedDrainPods | Pods annotated with rebalancing.cast.ai/prevented-drain=true. In the console: Pods that previously failed to drain. Also lets rebalancing target Nodes marked with rebalancing.cast.ai/status=drain-failed. |
ignoreLocalPersistentVolumes | Pods using local-path Persistent Volumes; their data does not move with them. |
WarningIgnoring these protections lets the Rebalancer evict pods that lose their progress (Job pods), never restart (bare pods), or were marked protected from eviction.
ignoreLocalPersistentVolumesadditionally results in data loss for applications using Local Persistent Volumes.
How aggressiveMode interacts with aggressiveModeConfig
aggressiveMode interacts with aggressiveModeConfigThese rules apply when you set the fields through the API or Terraform. The console offers no control for the deprecated aggressiveMode boolean.
aggressiveModeConfigis the recommended way to configure aggressive rebalancing. KeepaggressiveModeunset orfalsewhen using it.- If the deprecated
aggressiveModeistrue, it forces all four problematic-pod flags on. OnlyignoreLocalPersistentVolumesstill follows the config. - If only
aggressiveMode=trueis set, all four categories are ignored and Local Persistent Volumes stay protected. - To reproduce
aggressiveMode=truewith the config, set the fourignoreProblem*flags totrue. Local Persistent Volumes stay protected unless you also setignoreLocalPersistentVolumes.
Local Persistent Volumes configuration
By default, even in aggressive mode, nodes with Local Persistent Volumes (LPVs) are marked as "Not ready" for rebalancing. This is because LPVs are tied to specific nodes through node affinity rules (typically using the kubernetes.io/hostname topology label) and cannot be migrated between nodes.
You can configure aggressive mode to ignore these local volume constraints via the API or Terraform:
When creating or updating a rebalancing schedule through the API, include the aggressiveModeConfig in your request:
{
  "launchConfiguration": {
    "rebalancingOptions": {
      "aggressiveModeConfig": {
        "ignoreLocalPersistentVolumes": true
      }
    }
  }
}
This configuration allows rebalancing to include nodes with Local Persistent Volumes. For the full schema, see the Scheduled Rebalancing API Reference.
In Terraform, use the aggressive_mode_config block:
resource "castai_rebalancing_schedule" "example" {
  # Required configuration elements...

  launch_configuration {
    # Configure aggressive mode options
    aggressive_mode_config {
      # All flags except ignore_problem_prevented_drain_pods are required by the provider.
      ignore_local_persistent_volumes        = true
      ignore_problem_job_pods                = false
      ignore_problem_removal_disabled_pods   = false
      ignore_problem_pods_without_controller = false
      ignore_problem_prevented_drain_pods    = false
    }

    # Other launch configuration settings...
  }
}
For all provider options, see the Terraform Provider documentation.
WarningSetting
ignoreLocalPersistentVolumes(Terraform:ignore_local_persistent_volumes) totrueallows rebalancing to evict pods with local storage. This will result in data loss for applications using Local Persistent Volumes. Only use this option when data persistence is not critical.
Configuration examples
Using the API
Create a rebalancing schedule using the API:
{
  "schedule": {
    "cron": "*/30 * * * *"
  },
  "launchConfiguration": {
    "selector": {
      "nodeSelectorTerms": [
        {
          "matchExpressions": [
            {
              "key": "scheduling.cast.ai/spot",
              "operator": "Exists"
            }
          ]
        }
      ]
    },
    "rebalancingOptions": {
      "executionConditions": {
        "enabled": true,
        "achievedSavingsPercentage": 10
      },
      "minNodes": 2,
      "evictGracefully": false,
      "maxSimultaneousDrains": 5,
      "splitNodesInBatchesOf": 10
    },
    "targetNodeSelectionAlgorithm": "TargetNodeSelectionAlgorithmNormalizedPrice",
    "numTargetedNodes": 3,
    "nodeTtlSeconds": 300
  },
  "triggerConditions": {
    "savingsPercentage": 20
  },
  "name": "rebalance spots at every 30th minute"
}
The example sets evictGracefully to false for illustration only; false is the default, so you can omit the field.
maxSimultaneousDrains caps how many nodes drain at the same time. splitNodesInBatchesOf paces execution so that at most 10 extra nodes (created minus drained) are alive. Neither changes which nodes the plan selects; that is numTargetedNodes (Maximum batch size).
Alternatively, set targetedNodesPercentage in launchConfiguration to cap each rebalancing operation at a percentage of eligible nodes rather than a node count. See the Create Rebalancing Schedule API reference for the full field specification.
"launchConfiguration": {
  "targetedNodesPercentage": 50
}
The percentage is rounded up to a whole number of nodes, with at least one node selected, and takes precedence over numTargetedNodes. This allows reusing a single schedule across clusters that vary in size.
launch_configuration {
  targeted_nodes_percentage = 50
}
In Terraform, use targeted_nodes_percentage in launch_configuration instead of num_targeted_nodes — the two fields are mutually exclusive.
Using Terraform
Define a rebalancing schedule using the Terraform provider:
resource "castai_rebalancing_schedule" "spots" {
  name = "rebalance spots at every 30th minute"
  schedule {
    cron = "*/30 * * * *"
  }
  trigger_conditions {
    savings_percentage = 20
  }
  launch_configuration {
    # only consider instances older than 5 minutes
    node_ttl_seconds         = 300
    num_targeted_nodes       = 3
    rebalancing_min_nodes = 2
    evict_gracefully      = false
    # drain at most 5 nodes at the same time
    max_simultaneous_drains = 5
    # execute in batches, keeping at most 10 additional (created minus drained) nodes alive
    split_nodes_in_batches_of = 10
    selector = jsonencode({
      nodeSelectorTerms = [{
        matchExpressions = [
          {
            key      = "scheduling.cast.ai/spot"
            operator = "Exists"
          }
        ]
      }]
    })
    execution_conditions {
      enabled                     = true
      achieved_savings_percentage = 10
    }
  }
}
Updated 7 days ago